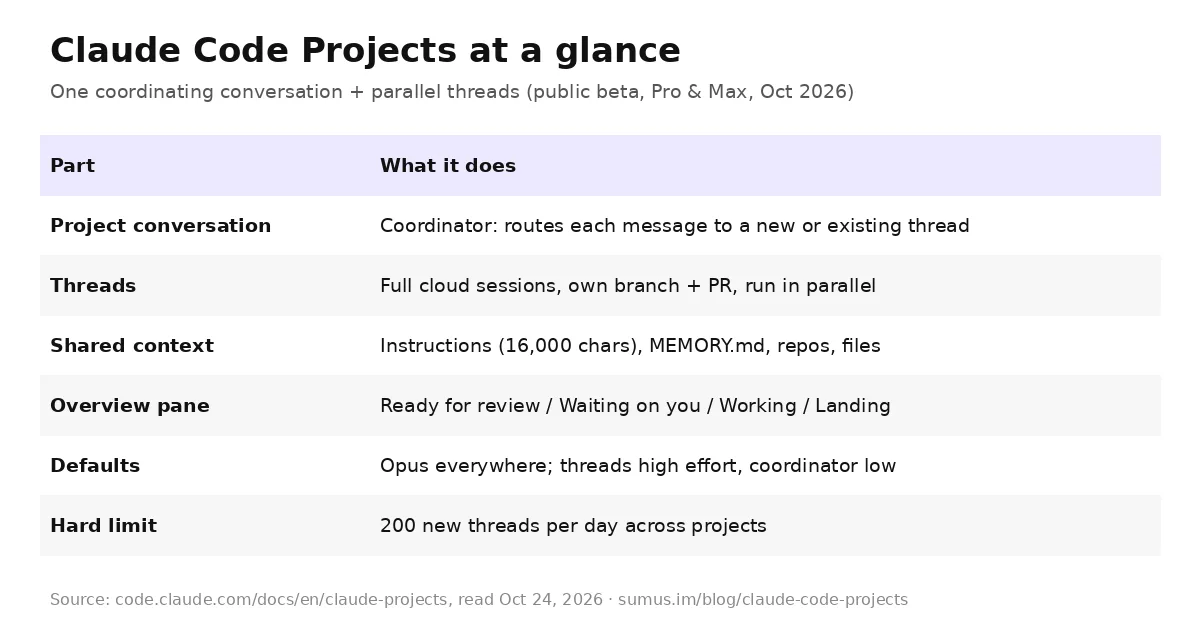
Claude Code Projects: Run Parallel Threads From One Chat
Claude Code Projects run one coordinating chat that starts parallel cloud threads with shared memory. How they work, setup, Pro/Max limits and when to use them.
Ideas, guides, and updates for working with AI teammates.
Claude Code Projects run one coordinating chat that starts parallel cloud threads with shared memory. How they work, setup, Pro/Max limits and when to use them.
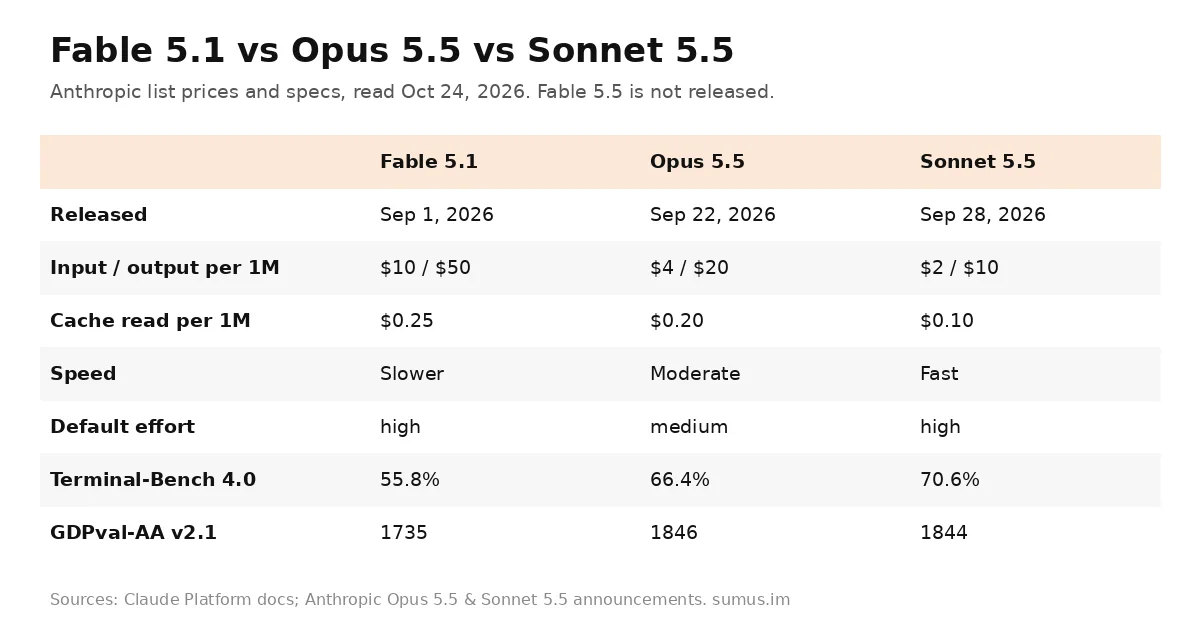
Fable vs Opus: Claude Fable 5.1 vs Opus 5.5 vs Sonnet 5.5 on price, speed and Anthropic benchmarks, plus which model to use. Fable 5.5 isn't out yet.
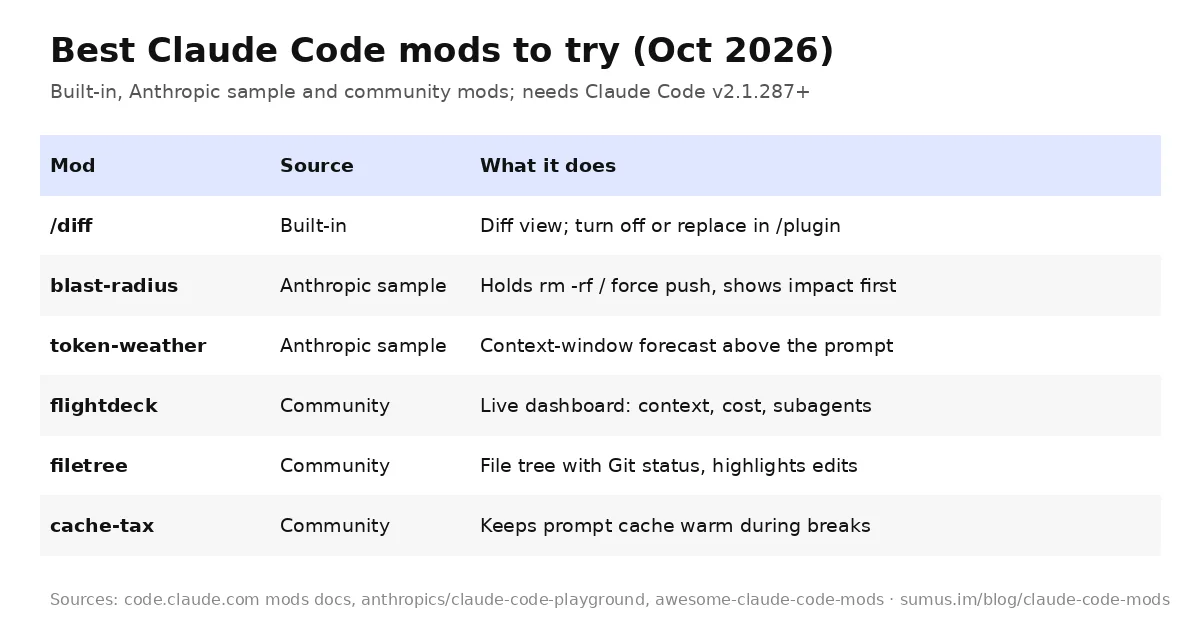
Claude Code mods are TypeScript functions in plugins that rewrite prompts, tool calls and UI. How they work, the best mods to try, and how to vet one first.
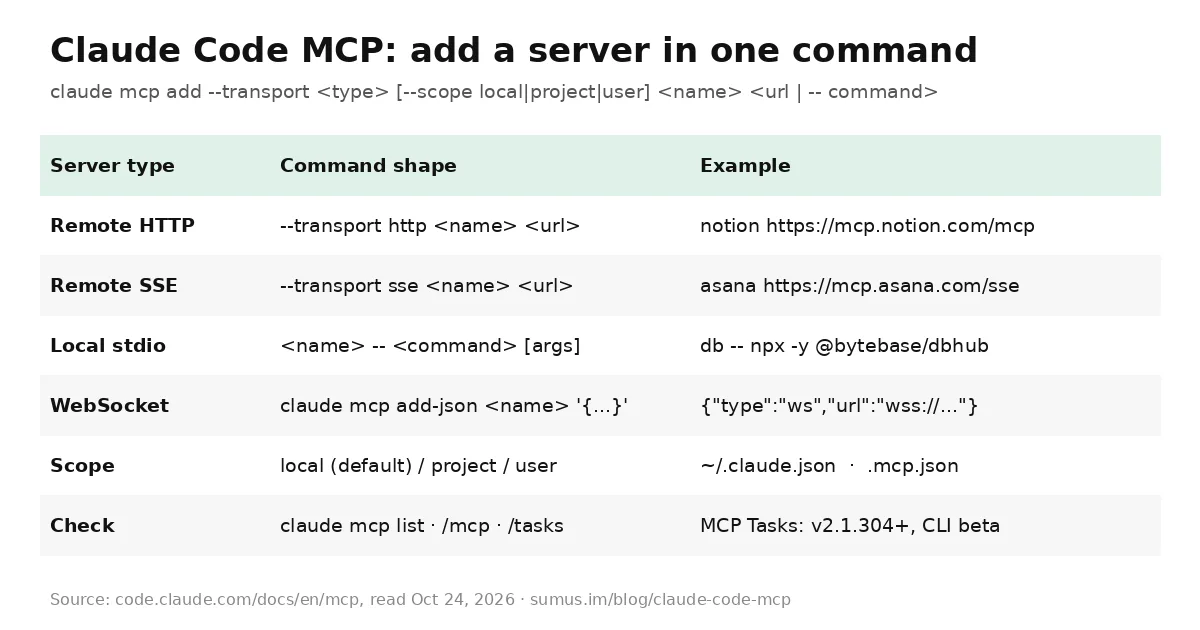
Claude Code MCP setup in one command: claude mcp add for HTTP, stdio and JSON servers, scopes, the best MCP servers, and the new MCP Tasks beta (v2.1.304+).
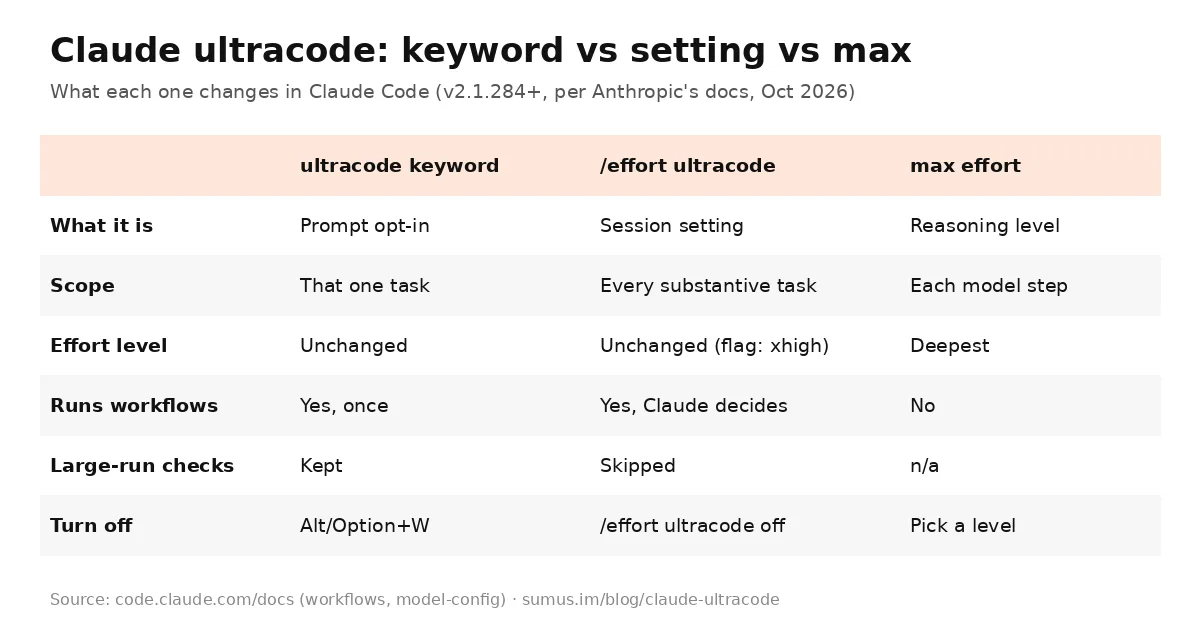
Claude ultracode runs dynamic workflows of parallel subagents in Claude Code. How it differs from max effort, what it costs on Pro and Max, and how to turn it off.
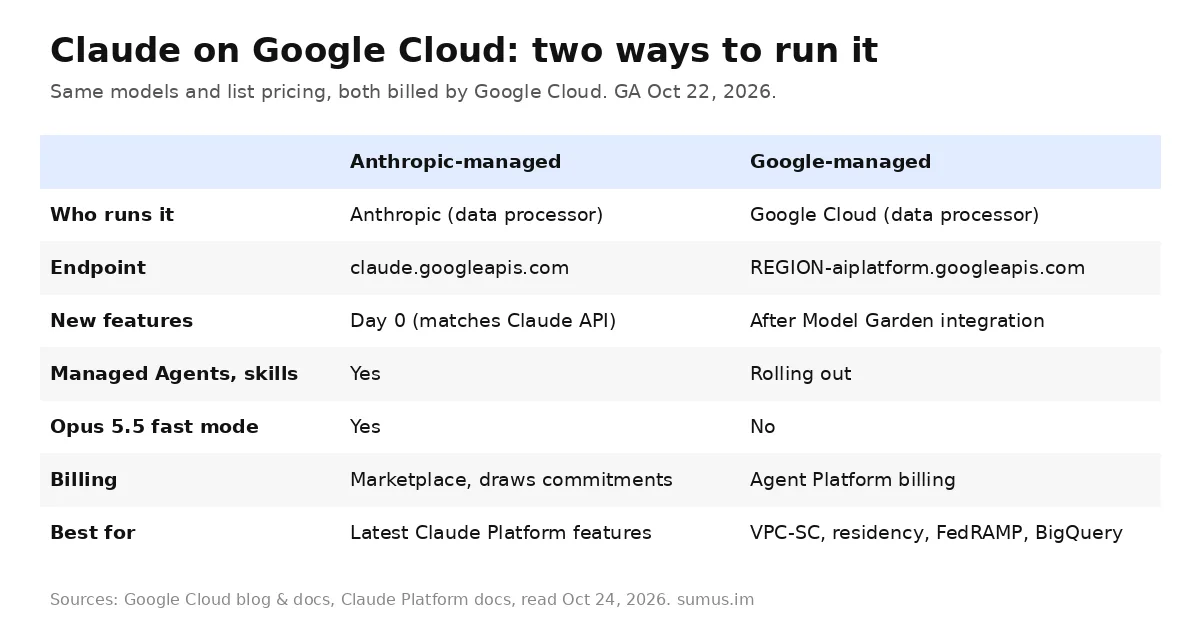
Claude on Google Cloud (Anthropic managed) went GA Oct 22, 2026. Setup steps, IAM roles, pricing, and Anthropic-managed vs Google-managed compared.
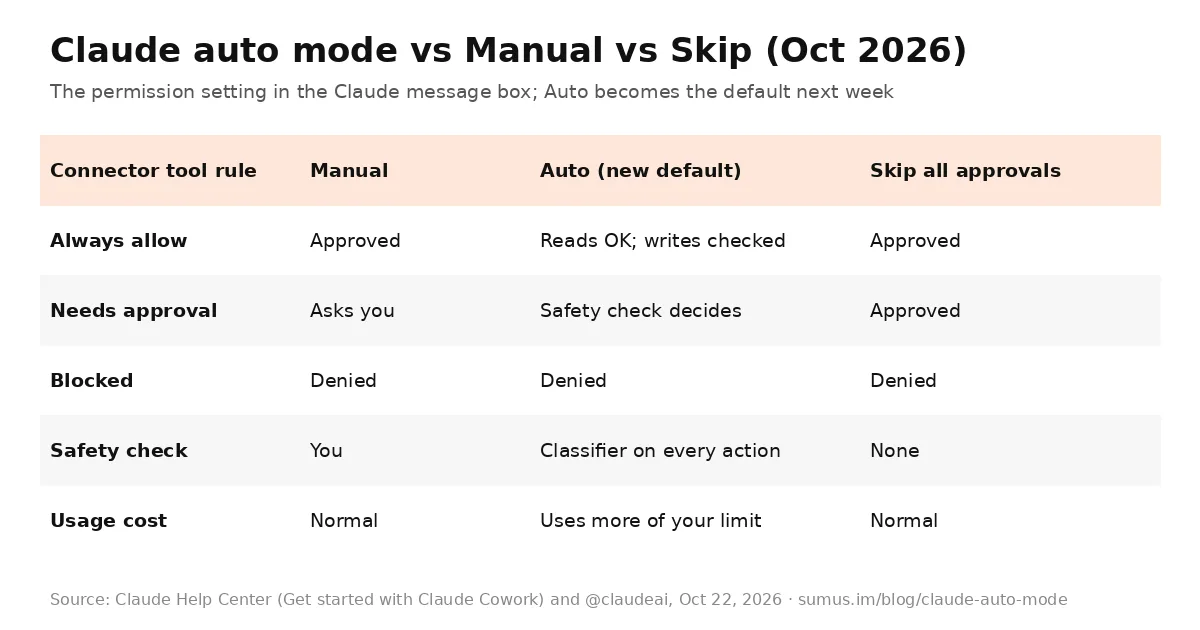
Claude auto mode becomes the default on Pro, Max and Team next week. What it does, how it differs from Claude Code auto mode, and how to switch back to Manual.
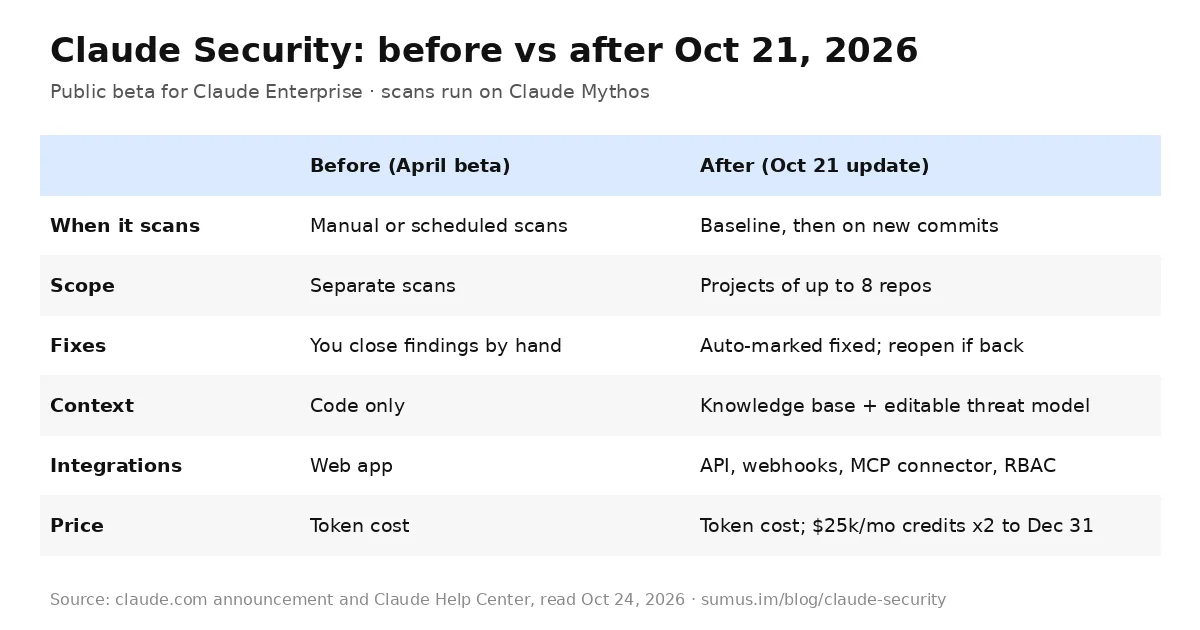
Claude Security now scans continuously, tracks fixes and spans 8-repo projects. What changed on Oct 21, 2026, how it works, pricing and the $25k credit offer.
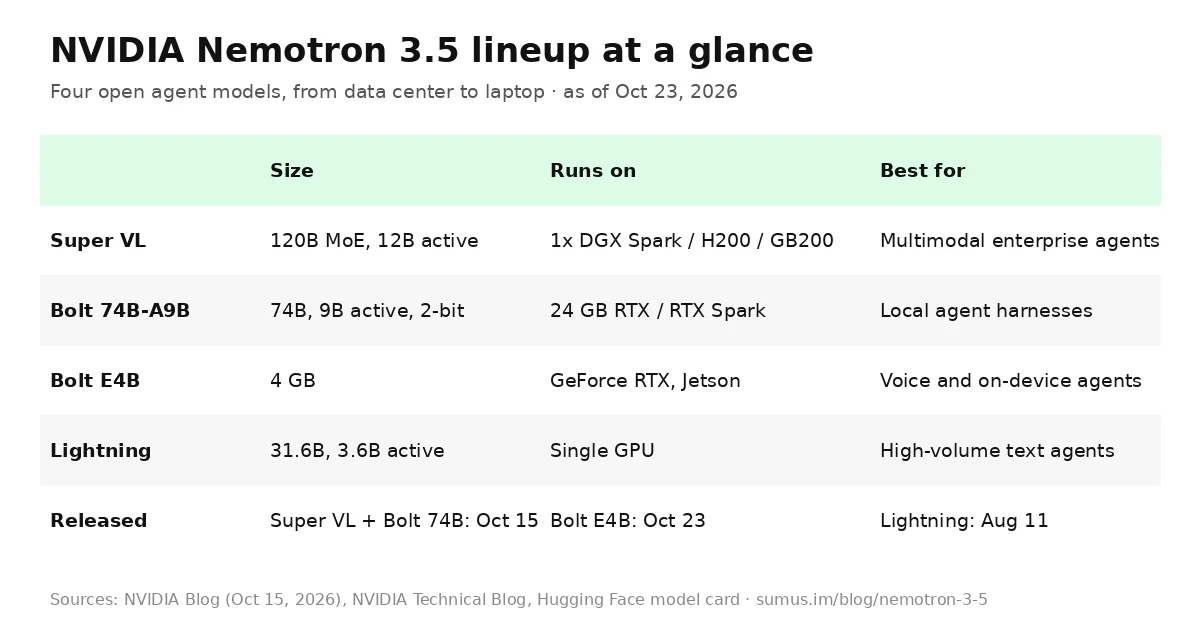
Nemotron 3.5 is NVIDIA's open agent model family: 120B Super VL with 1M context, Bolt for 24 GB PCs, Lightning. Specs, benchmarks, hardware, how to run.
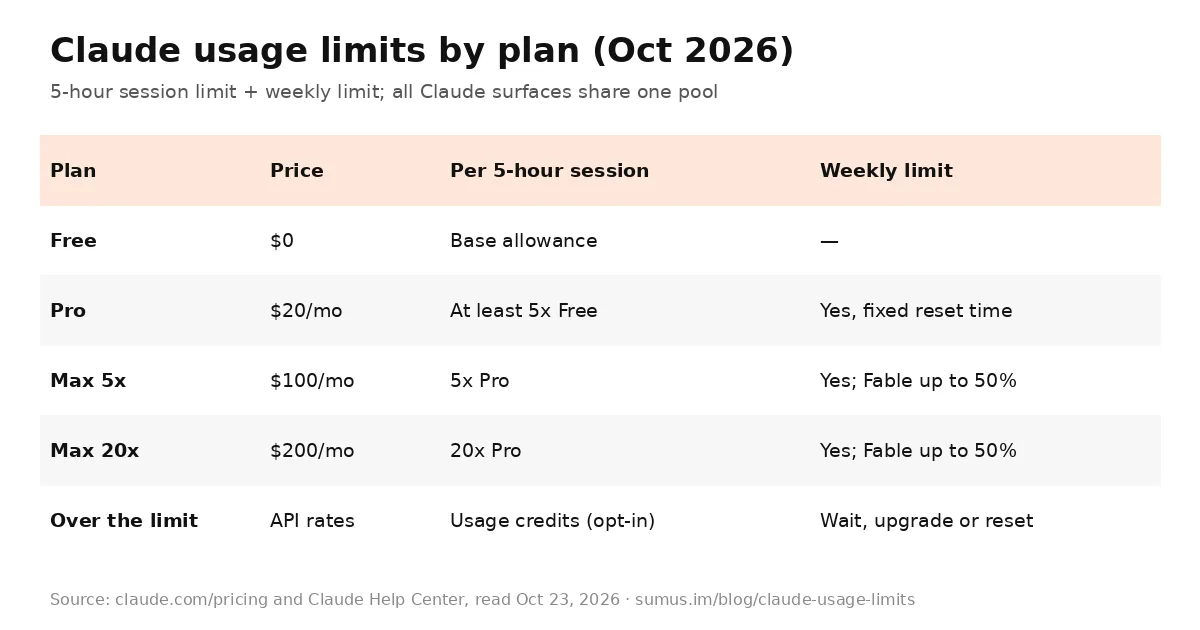
Claude usage limits reset every 5 hours plus a weekly cap. Pro, Max 5x and Max 20x limits, the Oct 2026 Max A/B test, and what to do when you hit them.
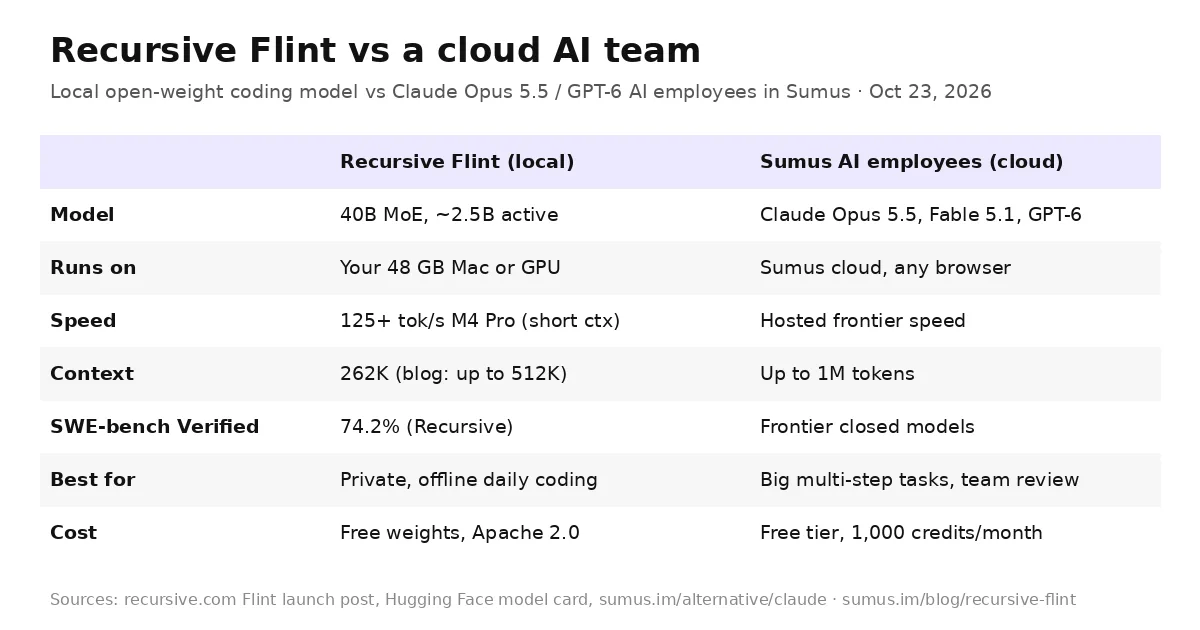
Recursive Flint is an open 40B MoE coding model with 2.5B active params: 74.2% SWE-bench Verified, 125+ tok/s on a MacBook. Specs, setup, local vs cloud.
DeepInfer is DeepSeek's Apache 2.0 inference engine behind V4.1 Flash: 26K decode tok/s per GPU, SM100 or Ascend 950, 128-GPU unit. Features, install, license.
Bring your ideas to Sumus and start working together.
Try it