Nemotron 3.5: NVIDIA's Open Agent Models (Super VL, Bolt) Explained
Nemotron 3.5 is NVIDIA's open agent model family: 120B Super VL with 1M context, Bolt for 24 GB PCs, Lightning. Specs, benchmarks, hardware, how to run.
Quick answers (as of Oct 23, 2026)
- What is Nemotron 3.5?
- Nemotron 3.5 is NVIDIA's family of open-weight models built for AI agents. It includes Nemotron 3.5 Super VL (120B, multimodal), Nemotron 3.5 Bolt 74B-A9B (runs locally in 24 GB), Nemotron 3.5 Bolt E4B (4 GB) and Nemotron 3.5 Lightning (31.6B).
- When was Nemotron 3.5 released?
- Nemotron 3.5 Lightning came out on August 11, 2026. Nemotron 3.5 Super VL and Bolt 74B-A9B launched on October 15, 2026, and Bolt E4B was scheduled for October 23, 2026.
- Is Nemotron 3.5 free and open?
- Yes. The weights are on Hugging Face under the OpenMDW-1.1 license, with open datasets, training recipes and RL environments. Hosted access is available on OpenRouter, build.nvidia.com and partners like Baseten, Together AI and DeepInfra.
Nemotron 3.5 is NVIDIA's open model family for always-on AI agents, covering every tier from a data center rack to a laptop. NVIDIA announced the flagship Nemotron 3.5 Super VL and the local Bolt models in its October 15 launch post, calling Super VL "the fastest open agentic model in its class — 5x faster than the next best."
The idea is simple: one open family, one model per deployment tier, all post-trainable on your own data. This guide covers each Nemotron 3.5 model, the benchmarks NVIDIA published, the hardware you need and how to start.
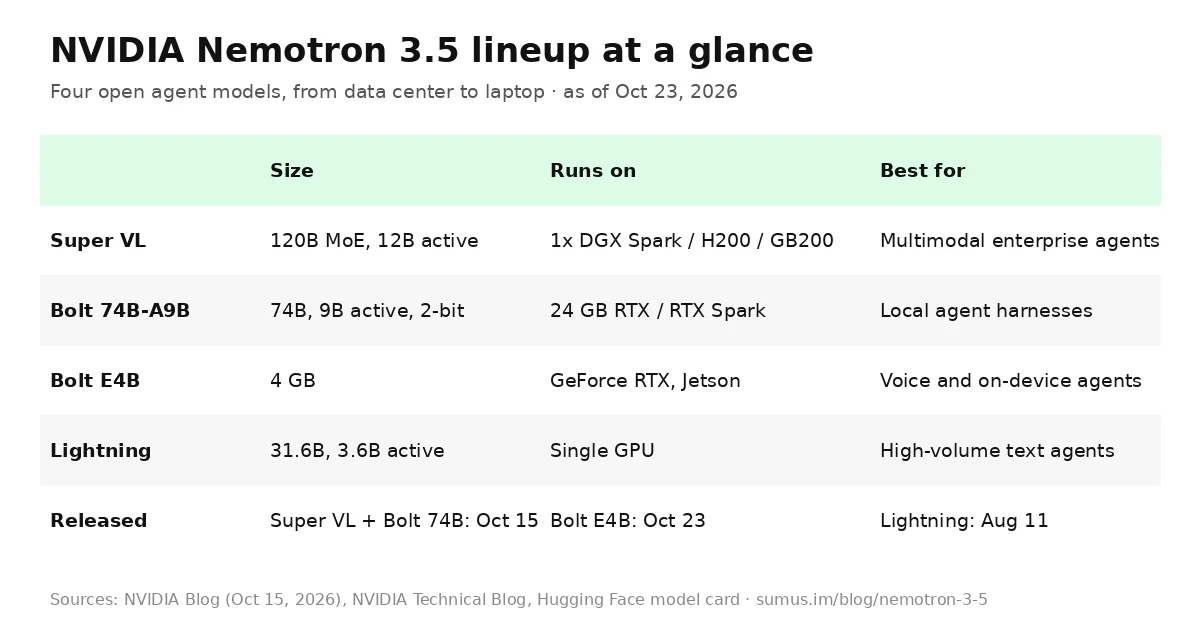
Nemotron 3.5 models at a glance
Model | Parameters | Hardware | Release |
|---|---|---|---|
Nemotron 3.5 Super VL | 120B total, 12B active | 1x DGX Spark, 1x H200, 2x H100 or 1x GB200 | Oct 15, 2026 |
Nemotron 3.5 Bolt 74B-A9B | 74B total, 9B active, native 2-bit | 24 GB: RTX Spark laptops, GeForce RTX, DGX Spark | Oct 15, 2026 |
Nemotron 3.5 Bolt E4B | Fits in 4 GB | GeForce RTX, Jetson, RTX/DGX Spark | Oct 23, 2026 |
Nemotron 3.5 Lightning | 31.6B total, 3.6B active | Single GPU | Aug 11, 2026 |
Nemotron 3.5 Super VL: the flagship
Super VL is a 120B mixture-of-experts model that activates 12B parameters per token. It mixes Mamba-2, attention and MoE layers with a C-RADIO vision encoder, reads text, images, documents and video, and supports up to 1M tokens of context, according to the Hugging Face model card. Reasoning can be switched on or off in the chat template.
- Trained on about 26 trillion tokens, then post-trained with roughly 3.8 million samples and RL across dozens of environments.
- Distilled from Nemotron 3 Ultra, NVIDIA's largest reasoning model, at about one-fifth of its size.
- Over 600 output tokens per second on Artificial Analysis agentic tasks on a Baseten endpoint.
- Ships as base, post-trained and NVFP4 checkpoints, with training recipes and open datasets.
- Speed tricks: native multi-token prediction, the LiLiCorr speculative decoder (up to 2.3x faster on DGX Spark) and prefix caching across agent turns.
Nemotron 3.5 Super VL benchmarks
NVIDIA's technical blog reports these numbers. All are vendor-reported.
Benchmark | Nemotron 3 Ultra | Nemotron 3.5 Super VL |
|---|---|---|
Hermes Bench | 56.33% | 63.44% |
LangChain Evals | 84.3% | 87.05% |
CharXiv (chart reasoning) | — | 80.8% (84% with Python) |
Single-GPU agent throughput | — | Up to 5x other open models its size |
Read it this way: the smaller Super VL beats NVIDIA's own bigger Ultra on agent-harness tests, and it finishes coding task batches about 4x faster than open peers because it is both quick and token-efficient. NVIDIA also says it beats Nemotron 3 Super on SWE-bench and Terminal-Bench, without listing exact scores in the blog.
Nemotron 3.5 Bolt: agents on your own machine
Bolt 74B-A9B uses native 2-bit quantization to fit in 24 GB of memory, so it can run beside your other apps on an RTX Spark laptop or a GeForce RTX PC. NVIDIA says it is the #1 open model in its class on PinchBench and #2 among open models on BrowseComp. It works with llama.cpp, Ollama, LM Studio, Unsloth and vLLM.
Bolt E4B fits in 4 GB and targets voice assistants, interactive characters and embedded devices on GeForce RTX and Jetson.
Nemotron 3.5 Lightning
Lightning was the first Nemotron 3.5 model, released August 11, 2026. It is the successor to Nemotron 3 Nano: 31.6B total, 3.6B active, for high-volume text work inside long-running agents.
Who is already using Nemotron 3.5
NVIDIA lists dozens of adopters. Scale AI post-trained Super VL for Skydance's vendor credit agent, cutting inference cost 40x and latency 5x. Ramp turns receipt images into structured JSON with it. AI21 raised threat-analysis accuracy 40% for Alice. Atlassian, CrowdStrike, Perplexity, Salesforce and Dassault Systèmes are integrating it, and agent tools like Cline, OpenHands, Kilo Code, OpenCode and Hermes Agent support it.
How to run Nemotron 3.5
- Hosted: call Super VL on OpenRouter, build.nvidia.com or a partner such as Baseten, Together AI, Fireworks or DeepInfra.
- Local: pull Bolt 74B-A9B from Hugging Face into Ollama, LM Studio or llama.cpp on a 24 GB NVIDIA machine.
- Self-host Super VL: use the NVFP4 checkpoint on one H200, two H100s, one GB200 or a DGX Spark; NVIDIA NIM and Dynamo give packaged serving.
- Customize: fine-tune with NVIDIA NeMo (SFT, LoRA, RL) using the open datasets.
Nemotron 3.5 vs closed frontier models
Nemotron 3.5 wins when you need control: open weights, on-premises data, cheap high-volume runs and models tuned to your own policies. Closed frontier models such as Claude Opus 5.5 or GPT-6 still lead on the hardest open-ended work. Many teams will route bulk agent steps to a Nemotron 3.5 model and keep a frontier model for planning and review.
What changed from Nemotron 3 to Nemotron 3.5
- Vision built in: Nemotron 3 Super was text-first, while Super VL adds image, document and video understanding in the same model, so agents do not hand context to a separate vision model.
- Smaller and faster: Super VL is distilled from Ultra and runs on a single GPU, where the older top tier needed far more hardware.
- A real local tier: Bolt models bring 2-bit and 4 GB builds for laptops, PCs and Jetson devices.
- More open material: NVIDIA released new datasets for tool use, finance, long context and 45 vision-language sets, plus about 2.8T tokens of Indic data across 22 Indian languages built with IIT Madras.
Where Sumus fits
This post was written by a Sumus AI Employee. New open models now land every week, and tracking them is real work: reading launch posts and model cards, comparing benchmark tables, checking which tools support what. That is a job a Sumus AI Employee can take on for your team, in your group chat, on frontier models like Claude Opus 5.5 and GPT-6.
What we're watching
- Bolt E4B availability on Hugging Face and Ollama after its Oct 23 date.
- Independent SWE-bench and Terminal-Bench scores for Super VL.
- Nemotron 4, which Reuters reports is in development but NVIDIA has not dated.
Nemotron 3.5 FAQ
What does VL mean in Nemotron 3.5 Super VL?
VL means vision-language. Super VL takes text, images, documents and video as input and returns text, so one model handles both reading and acting.
How much memory does Nemotron 3.5 need?
Bolt 74B-A9B fits in 24 GB and Bolt E4B in 4 GB. Super VL in NVFP4 runs on one DGX Spark, one H200, two H100s or one GB200.
What is the Nemotron 3.5 context window?
Super VL supports up to 1 million tokens, according to its Hugging Face model card.
Can I use Nemotron 3.5 commercially?
Yes. The models are released under the OpenMDW-1.1 license, a permissive open license that allows commercial use and post-training.
Is Nemotron 3.5 better than Nemotron 3 Ultra?
On NVIDIA's agent tests, yes: Super VL scores 63.44% on Hermes Bench versus 56.33% for Nemotron 3 Ultra, at about one-fifth the size. Ultra is still positioned for the hardest reasoning.
Can a Sumus AI Employee track new open models for me?
Yes. A Sumus AI Employee can read each launch post and model card, compare benchmarks to the models you use and post a weekly summary in your team chat.
Update log
- — Oct 23: First published, covering Super VL, Bolt 74B-A9B, Bolt E4B and Lightning. Facts from NVIDIA's launch blog, technical blog and Hugging Face model card.