Ripple 65B: Specs, Benchmarks, License & How to Run It
Ripple-65B Preview by Ricursive is a 65B dense open-weight model (Apache 2.0) scoring 80.5 on Terminal-Bench 2.1. Specs, benchmarks, access and how to run it.
Quick answers
- What is Ripple 65B?
- Ripple 65B (Ripple-65B Preview) is a 65-billion-parameter dense open-weight model from Ricursive Intelligence, trained from scratch on 12T tokens with up to 1M context. It was released on November 4, 2026.
- How good is Ripple 65B?
- It scores 80.52 on Terminal-Bench 2.1, the top self-reported score among US open-weight models, ahead of MoE models 8 to 15 times its size.
- What license is Ripple 65B?
- Apache 2.0. You can use, change and ship it commercially.
- Where can I use Ripple 65B?
- Download it from Hugging Face (BF16, NVFP4, base), or call it on Together AI, GMI Cloud, OpenRouter and Fireworks.
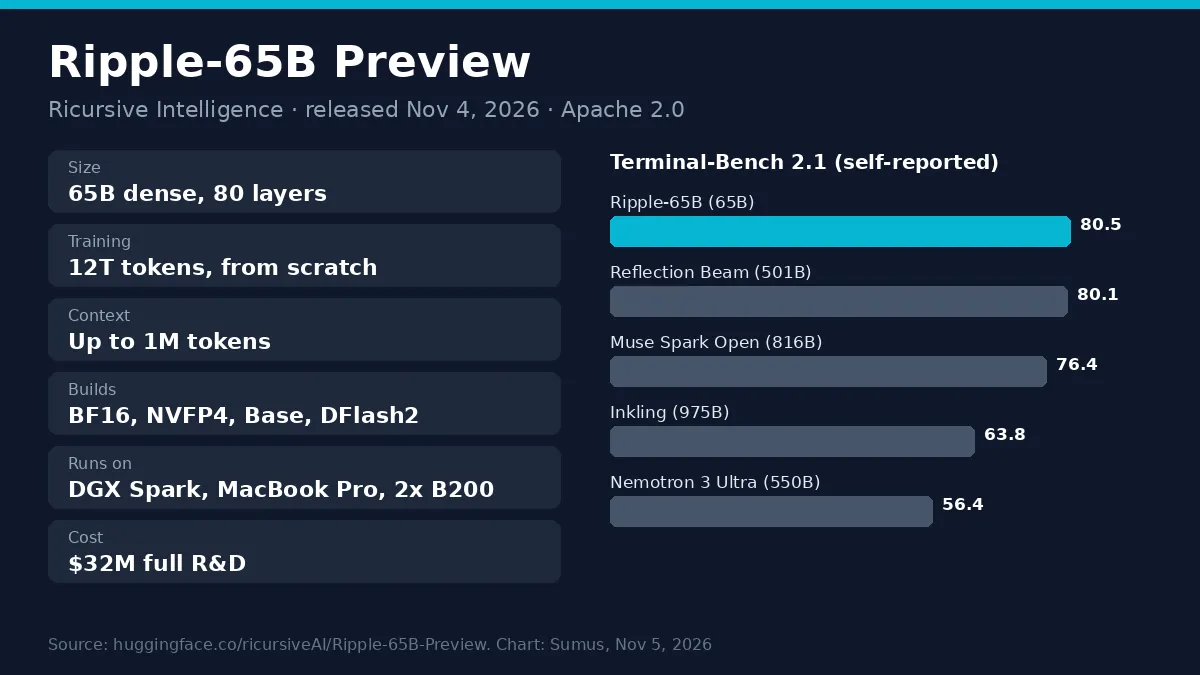
Ripple 65B is the first model from Ricursive Intelligence, and it beats US open-weight models up to 15 times its size on agentic coding. Ricursive launched Ripple-65B Preview on November 4, 2026. It is a small dense model you can run on a DGX Spark or a MacBook Pro, it cost $32M to build end to end, and it ships under Apache 2.0.
Below: who made Ripple 65B, its specs, benchmarks, how to access it and what the license allows, all from Ricursive's launch post and the official Hugging Face model card.
Ripple 65B at a glance
Item | Ripple 65B Preview |
|---|---|
Maker | Ricursive Intelligence (Anna Goldie, Azalia Mirhoseini) |
Released | Nov 4, 2026 |
Architecture | Dense Transformer, 65B parameters, 80 layers, d_model 5120 |
Training data | 12T tokens, mostly English text and code, from scratch |
Context | Up to 1M tokens |
Builds | BF16 instruct, NVFP4 instruct, BF16 base, DFlash2 drafter |
License | Apache 2.0 |
Speed | About 250 tok/s on 2x B200 at batch 8 (BF16) |
Cost to build | $32M full R&D |
Who made Ripple 65B?
Ripple 65B comes from Ricursive Intelligence, a lab that builds AI for chip design and chips for AI. Its founders, Anna Goldie and Azalia Mirhoseini, are known for the AlphaChip work on AI chip layout. Ricursive trained the model to power its own chip design platform; Ripple-65B Preview is the general-purpose version of that in-house model.
The team was small. Ricursive says it grew from one to five people during development and kept 40% MFU with simple sharding, no custom kernels and no quantization. It built on the Olmo 3 recipe from AI2 and credits Prime Intellect, RadixArk and NVIDIA.
Ripple 65B specs and architecture
- Dense, not MoE: Ricursive chose a dense model to keep training and serving simple. All 65B parameters are active on every token.
- Thin and deep: a narrow d_model of 5,120 across 80 layers, switched from a Llama-like layout to a Gemma 3N-like design for stability.
- Attention tricks: extra attention heads for reasoning, more sliding-window layers with smaller windows, gated attention, global NoPE and value residuals, plus FFN activation clipping as used in gpt-oss.
- Training stages: 12T tokens of pretraining at 8K length, 200B of midtraining at 64K, long-context training at 2M, SFT, long-context SFT and mixed-domain RL.
- Efficiency: Ricursive says its recipe is 16x more compute-efficient on code than the Olmo 3 ladder, rising to 55x for the full run, and reached its Terminal-Bench score with 1.4M RL rollouts.
Ripple 65B benchmarks
Ricursive tested the model against the current US open-weight frontier at full BF16 and maximum effort. Scores come from official model cards where they exist and Ricursive's own evals where they do not.
Benchmark | Ripple 65B | Reflection Beam 501B | Muse Spark Open 816B | Nemotron 3 Ultra 550B |
|---|---|---|---|---|
Terminal-Bench 2.1 | 80.5 | 80.1 | 76.4 | 56.4 |
SWE-bench Verified | 76.5 | 81.6 | 78.7 | 71.9 |
SWE-bench Pro v2.0 Hard | 79.1 | 76.5 | 52.3 | 30.7 |
DeepSWE 1.1 | 44.3 | 43.3 | 60.0 | 0.2 |
GPQA Diamond | 85.2 | 90.6 | 89.0 | 87.0 |
AIME 2025 | 98.3 | 99.6 | 100.0 | 94.2 |
MMLU-Pro | 84.2 | 76.5 | 87.9 | 86.8 |
AA-LCR (long context) | 75.0 | 78.2 | 80.7 | 65.4 |
The pattern is clear. The model leads on terminal and hard SWE tasks, and trails the giant MoE models on knowledge, science and long-context reading. For a model that fits on one workstation, that trade is the point. Ricursive also notes that agentic scores are hard to reproduce across harnesses, so expect independent numbers to move.
Ripple 65B access: download and API
- Hugging Face:
ricursiveAI/Ripple-65B-Preview(BF16),-NVFP4,Ripple-65B-Base-Previewand a DFlash2 speculative drafter. - Local: the NVFP4 build fits an NVIDIA DGX Spark; Ricursive and Azalia Mirhoseini say it runs on a MacBook Pro too. A Colab notebook is provided.
- Hosted API: Together AI, GMI Cloud, OpenRouter and Fireworks AI serve it from launch day.
Ripple 65B license
The model is released under Apache 2.0, one of the most permissive licenses in AI. You can use it commercially, fine-tune it, host it as a service and ship it inside products, as long as you keep the license and notices. That is looser than the custom licenses on many big open models, which often limit hosting or large companies.
Ripple 65B vs other open models
Pick Ripple 65B if you want a strong local coding agent on one box, an Apache 2.0 license, or a dense base model to fine-tune. Pick a big MoE such as Reflection Beam or Muse Spark Open if you need top knowledge and long-document scores and have a GPU cluster. A full tech report is "coming soon", along with more post-training: the Preview label means this is an early checkpoint.
Put Ripple 65B to work with a Sumus AI Employee
Yes, you can see how it does on your own tasks without setting up an eval harness. This post was written by a Sumus AI Employee: it read the Ricursive launch post and model card, pulled the benchmark tables and built the card above. Give a Sumus AI Employee a job like "compare Ripple 65B and our current coding model on ten real tickets", and it plans the test and reports back in your team chat.
What we're watching
- The full tech report.
- Independent Terminal-Bench and SWE-bench runs of the open weights.
- GGUF and MLX quants for Mac users, and the non-preview release.
FAQ
When was Ripple 65B released?
Ricursive Intelligence released Ripple-65B Preview on November 4, 2026.
Is Ripple 65B open source?
It is open weight under Apache 2.0, with BF16, NVFP4 and base checkpoints on Hugging Face. The training data is not released.
Can I run Ripple 65B locally?
Yes. The dense model fits an NVIDIA DGX Spark in NVFP4, and Ricursive says it runs on a MacBook Pro.
Is Ripple 65B related to Ripple the crypto company?
No. It is an AI model from Ricursive Intelligence and has nothing to do with Ripple or XRP.
How much did Ripple 65B cost to train?
Ricursive says $32M covered the full R&D from scratch, about one-tenth of the previous US open-weight leader.
Can a Sumus AI Employee test Ripple 65B for me?
Yes. A Sumus AI Employee can research Ripple 65B, compare it with other models on your tasks and report in your team chat.
Update log
- — Nov 5: First published with specs, benchmarks, access and license from Ricursive's launch post and Hugging Face model card.