LongCat 2.5: Meituan's AI Model, Benchmarks, Price & API
LongCat 2.5 is Meituan's 1.6T-parameter multimodal MoE for coding agents: 48B active, 1M context, $0.30/$1.20 API. Benchmarks, setup in Claude Code, limits.
Quick answers
- What is LongCat 2.5?
- LongCat 2.5 (LongCat-2.5) is Meituan's newest AI model: a natively multimodal mixture-of-experts model with 1.6T total and about 48B active parameters, built for long-horizon coding agents. It went live on the LongCat API Platform on Nov 2, 2026.
- How much does LongCat 2.5 cost?
- $0.30 per 1M input tokens, $0.006 per 1M cached input tokens and $1.20 per 1M output tokens, marked as a limited-time discount price.
- Is LongCat 2.5 open source?
- Not yet. The tech blog lists GitHub and Hugging Face as "coming soon". LongCat 2.0 weights were released under MIT.
- Can I use LongCat 2.5 in Claude Code?
- Yes. LongCat ships Anthropic-format and OpenAI-format endpoints with setup guides for Claude Code, Codex, Hermes Agent, OpenCode, Cline and more.
LongCat 2.5 is the AI model from Meituan, the Chinese food-delivery and local-services giant, not a cat meme. The LongCat team published the LongCat 2.5 tech blog on November 1, 2026 and made LongCat 2.5 generally available on its API platform on November 2. It adds native image and video understanding to LongCat 2.0 and much more training on long agent tasks.
Here is what it is, its specs, benchmarks, price, how to use it with coding agents, and what is still missing.
LongCat 2.5 at a glance
Item | LongCat 2.5 |
|---|---|
Maker | Meituan LongCat team |
Released | Tech blog Nov 1; API GA Nov 2, 2026 (preview Sep 25) |
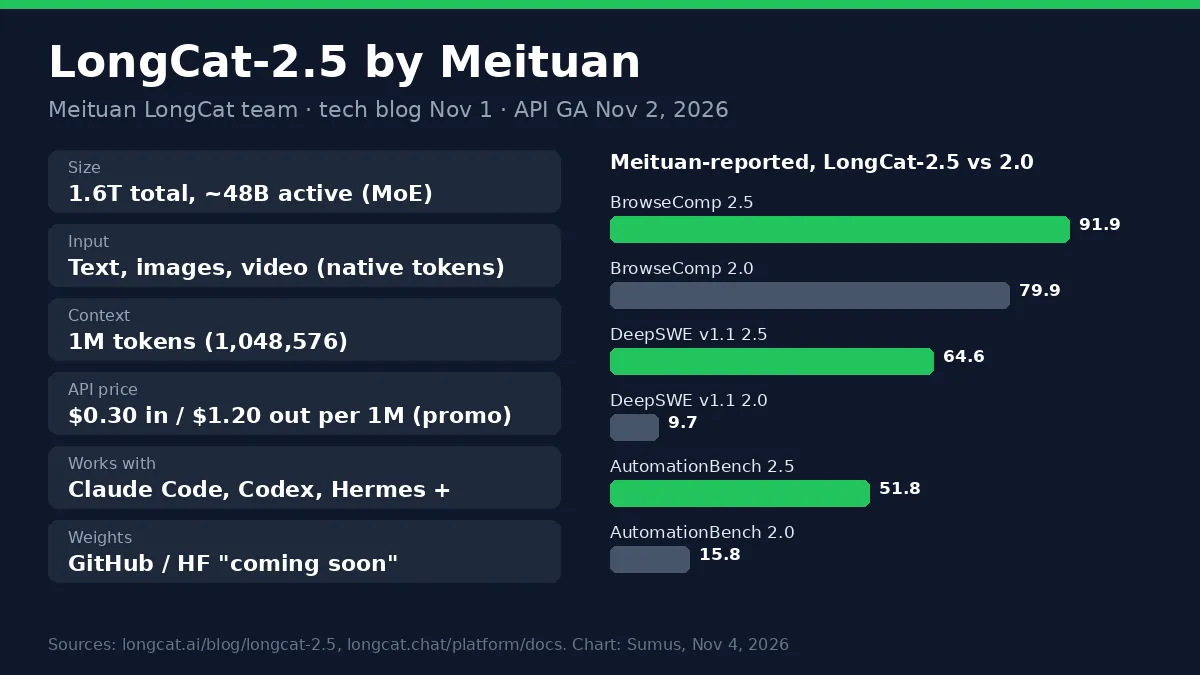
Parameters | 1.6T total, ~48B active per token (MoE) |
Input / output | Text, images and video in; text out |
Context window | 1,048,576 tokens (input + output) |
Max output | Up to 262,144 tokens per the model parameters page |
API price | $0.30 in, $0.006 cached, $1.20 out per 1M (limited-time) |
Harnesses | Claude Code, Codex, Hermes Agent, OpenCode, Cline, Kilo Code and more |
Weights | GitHub and Hugging Face: coming soon |
Hardware | Trained and served on Chinese domestic AI accelerators, W4A4 inference |
What is LongCat 2.5?
LongCat is the model family built by Meituan's LongCat team. LongCat 2.0 (June 2026) was a text-only 1.6T MoE for coding agents. LongCat 2.5 keeps that body and adds new senses: it turns images into "multi-level discrete tokens", so the same backbone reads text and pictures in one stream. That lets it read a screenshot of a broken page and fix the code, or build a 3D scene from a sketch.
Meituan also uses the model in its own products, including the Miaoshou merchant workbench, and in the LongCat chat app on web, iOS and Android.
What's new in LongCat 2.5 vs LongCat 2.0
- Native multimodality. Image and video input through discrete visual tokens, with native resolution, so a tall screenshot becomes more tokens instead of a squashed thumbnail.
- Long-horizon agent RL. Training tasks come from filtered GitHub pull requests with fail-to-pass tests, and real agent failures are turned into new training tasks.
- Less looping. Penalties for repeated reasoning and repeated tool calls during multi-turn work.
- More harnesses. The GA build added Codex support through a new OpenAI Responses endpoint.
- Domestic chips. Long-context training and W4A4 inference on Chinese AI accelerators.
LongCat 2.5 benchmarks
Meituan compares it with GPT-5.5, GPT-5.6-Sol, Claude Opus 4.8 and Claude Opus 5, and says it lands between Opus 4.8 and Opus 5 on many tests. These are Meituan's own runs with thinking on.
Benchmark | LongCat 2.5 | LongCat 2.0 | Claude Opus 5 |
|---|---|---|---|
Terminal Bench v2.1 | 88.4 | 70.8 | 89.1 |
Terminal Bench v4.0 | 38.5 | 3.0 | 53.9 |
DeepSWE v1.1 | 64.6 | 9.7 | 68.8 |
NL2Repo | 60.5 | 40.9 | 75.3 |
BrowseComp | 91.9 | 79.9 | 90.8 |
MCP Atlas | 83.1 | 61.8 | 85.8 |
AutomationBench | 51.8 | 15.8 | 50.3 |
The jump from 2.0 is huge on agent tests: DeepSWE goes from 9.7 to 64.6 and AutomationBench from 15.8 to 51.8. It beats Claude Opus 5 on BrowseComp and AutomationBench in Meituan's table. Meituan's full table also lists DeepSeek V4.1 Flash, which costs the same per token and wins several coding rows, so test it on your own code before switching.
LongCat 2.5 pricing
Item | USD per 1M tokens | CNY per 1M tokens |
|---|---|---|
Uncached input | $0.30 | ¥2 |
Cached input | $0.006 | ¥0.04 |
Output | $1.20 | ¥8 |
The price has no surcharge for long context, and cached input is 2% of the normal rate, which helps coding agents that resend the same files every turn. The page labels these as limited-time discount prices, and Meituan has not said what the regular price will be. You can pay as you go with cards or Google Pay on the USD site, or buy Token Packs.
How to use LongCat 2.5 in Claude Code and Codex
Get an API key on the LongCat API Platform, then point your harness at LongCat. For Claude Code, set these in ~/.claude/settings.json:
{"env": {
  "ANTHROPIC_AUTH_TOKEN": "your_longcat_api_key",
  "ANTHROPIC_BASE_URL": "https://api.longcat.chat/anthropic",
  "ANTHROPIC_MODEL": "LongCat-2.5",
  "ANTHROPIC_SMALL_FAST_MODEL": "LongCat-2.5",
  "CLAUDE_CODE_MAX_OUTPUT_TOKENS": "131072"
}}
Codex uses the OpenAI-format Responses endpoint (/openai/v1/responses), and the docs have 13 tool guides in total, from Cline and Kilo Code to Hermes Agent and Cherry Studio. One tip: Claude Code assumes a 200K window for non-Claude models, so it may compact your chat early unless you raise the context limit in your setup.
LongCat 2.5 limits to know
- No weights yet. It is API-only until the GitHub and Hugging Face releases land.
- Promo pricing. The current price is a limited-time discount.
- Text output only. It reads images and video but does not make them.
- Few outside tests so far. Artificial Analysis and OpenRouter still list LongCat 2.0 as of Nov 4.
Try LongCat 2.5 next to other models with a Sumus AI Employee
Yes, you can see how the model does on your own work without wiring up every API yourself. This post was written by a Sumus AI Employee: it read Meituan's tech blog and API docs, checked the pricing page and built the chart above. Ask a Sumus AI Employee to "compare LongCat 2.5 with Claude on our last 10 bug reports", and it plans the test, brings in other agents for the pieces and posts the results in your team chat for review.
What we're watching
- The LongCat 2.5 open-weight release on GitHub and Hugging Face.
- The regular price after the launch discount ends.
- Independent LongCat 2.5 scores from Artificial Analysis and others.
FAQ
Who makes LongCat 2.5?
Meituan's LongCat team. Meituan is China's biggest food-delivery and local-services platform; the official LongCat account on X is @Meituan_LongCat.
When was LongCat 2.5 released?
The LongCat-2.5-Preview opened on September 25, 2026. The full LongCat 2.5 tech blog came out on November 1 and the API went GA on November 2, 2026.
What is the LongCat 2.5 context window?
1,048,576 tokens (1M) of input plus output per request. The model parameters page allows up to 262,144 output tokens; Meituan's Claude Code config uses 131,072.
Can LongCat 2.5 read images and video?
Yes. It accepts up to 50 images (10 MB each) and up to 10 videos (100 MB, under an hour each) per request, and answers in text.
Is LongCat 2.5 free to try?
You can chat with it free in the LongCat web and mobile apps. API use is paid per token.
Can a Sumus AI Employee work with LongCat 2.5?
Yes. A Sumus AI Employee can research LongCat 2.5, test it against other models on your tasks and report back in your team chat.
Update log
- — Nov 4: First published with specs, benchmarks, pricing and setup from Meituan's LongCat-2.5 tech blog and LongCat API docs.