Mistral Large 4: Specs, Benchmarks, API Price & License
Mistral Large 4 (Le Chonk) is a 1.05T-parameter open-weight MoE with 52B active and 1M context. Benchmarks, $0.70/$2.10 API price, license and how to run it.
Quick answers
- What is Mistral Large 4?
- Mistral Large 4 (nicknamed "Le Chonk", or ML4) is Mistral AI's biggest model: a natively multimodal mixture-of-experts model with 1.05T total and 52B active parameters and a 1M-token context window. The preview API opened on Oct 6, 2026.
- Is Mistral Large 4 open weight?
- Yes. The weights landed on Hugging Face on Oct 29, 2026 in FP8 and NVFP4 builds, under the Mistral Ecosystem Open-Weight License.
- How much does the Mistral Large 4 API cost?
- $0.70 per 1M input tokens, $0.07 per 1M cached input tokens and $2.10 per 1M output tokens on Mistral Studio.
- What is Mistral Large 4 best at?
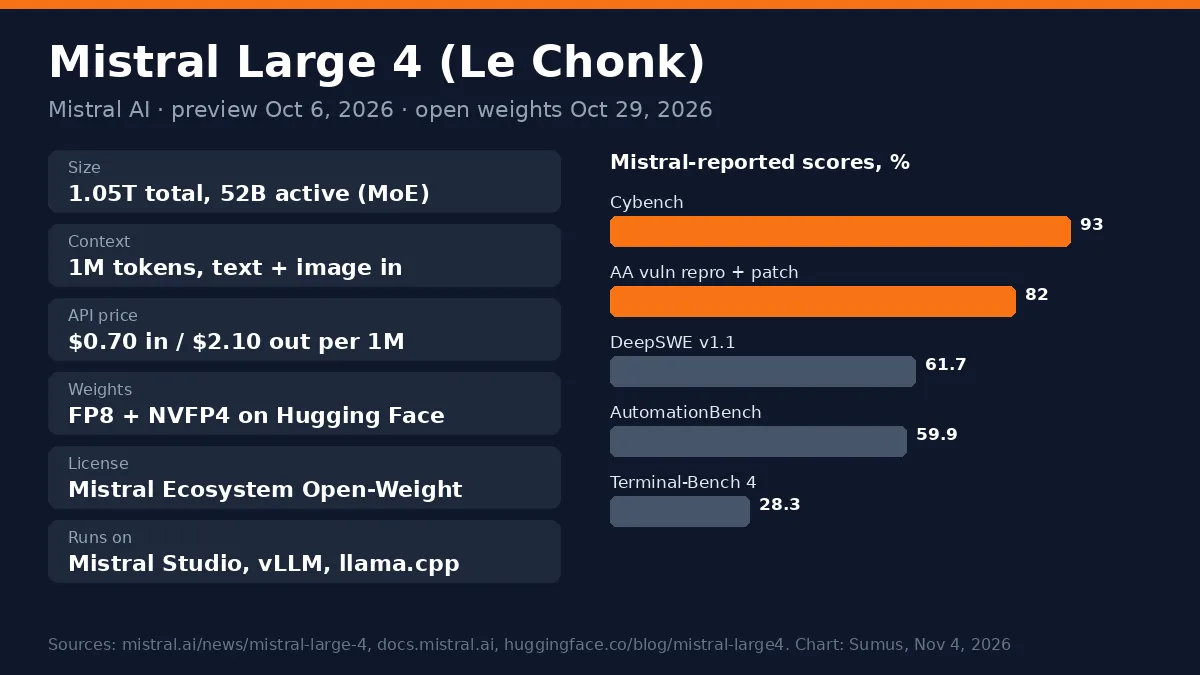
- Agentic coding and cybersecurity. Mistral reports 93% on Cybench, 82% on the AA vulnerability reproduce-and-patch test and 61.7% on DeepSWE v1.1.
Mistral Large 4 is the largest open-weight model ever shipped by a European lab, and the first Mistral model built to compete with the top open models from China. Mistral announced Mistral Large 4 on October 6, 2026 as a public preview API, then released the weights on October 29, which is when search interest jumped.
This guide covers what it is, its specs, benchmarks, API price, license and how to run it, with numbers from Mistral's launch post, the official model docs and the Hugging Face release.
Mistral Large 4 at a glance
Item | Mistral Large 4 |
|---|---|
Maker | Mistral AI (Paris) |
Nickname | Le Chonk, ML4 |
Preview API | Oct 6, 2026 on Mistral Studio |
Open weights | Oct 29, 2026 (FP8, NVFP4) |
Parameters | 1.05T total, 52B active (49B without embeddings) |
Input / output | Text and images in, text out |
Context window | 1M tokens |
API price | $0.70 in, $0.07 cached, $2.10 out per 1M tokens |
License | Mistral Ecosystem Open-Weight License |
Training | From scratch on 3,800 NVIDIA Grace Blackwell GPUs in Europe |
What is Mistral Large 4?
Mistral Large 4 is a general-purpose model with reasoning always on. It reads text and images, writes text, calls functions, returns structured output and runs agents through Mistral's Agents API. Mistral calls it "our largest and most capable model to date" and says it will be the base for a new family of specialized Mistral models.
Two things make Mistral Large 4 stand out. First, it is open weight at frontier scale, so companies can run it on their own servers. Second, Mistral trained it for security work that closed models often refuse, like reproducing a real bug before patching it. More than 160 languages were in the training data, including every official EU language.
Mistral Large 4 specs and architecture
Hugging Face's launch post gives the full layout:
- 72 decoder layers, hidden size 6,144, 64 attention heads.
- Mixture of experts: 128 experts, a router picks 4 per token, plus 1 shared expert, so 5 experts run per token. The first layer is dense.
- Two kinds of sparsity: Multi-head Latent Attention with a DeepSeek Sparse Attention indexer that picks up to 2,048 earlier positions for each query.
- Vision: a 1.6B Pixtral encoder (30 layers, 14×14 patches).
- Reasoning effort: low, medium or high. High is the default and reasoning cannot be turned off.
Mistral Large 4 benchmarks
All scores below are from Mistral's launch post and the Hugging Face blog. Several are independent tests run by Artificial Analysis and Vals AI.
Benchmark | Mistral Large 4 | What it means |
|---|---|---|
Cybench (40 CTF tasks) | 93% | One of the best open-weight scores |
AA vuln reproduce + patch | 82% | Highest of any model on this test |
DeepSWE v1.1 | 61.7% | Real software engineering tasks |
SWE-Atlas-QnA | 59.4% | Repository understanding |
Terminal-Bench 4 | 28.3% | Hard terminal workflows |
Coding Agent Index | 49.8% | Ahead of DeepSeek V4 Pro 0813 and Qwen3.8 Max |
AutomationBench | 59.9% | 657 business workflows (Gmail, Sheets, Slack, Salesforce) |
AA-Briefcase | 1,393 Elo | Long-horizon knowledge work |
Lakera B3 | 93.3% attacks resisted | Prompt-injection robustness |
Dense 200 (visual grounding) | 42% | Above GPT-6 Astra (41%) |
In a blind coding review with Surge AI, Mistral Large 4 Preview scored 3.74 out of 5, second of five models, behind Claude Opus 5 (4.22) and ahead of Kimi K3 (3.59) and GLM-5.3 (3.60). As of October 29, Hugging Face says it was the fifth-best open-weight model on the Artificial Analysis Intelligence Index. Vals AI ranks the open-weight build #17 of 30 on its Vals Index at 56.42%.
Mistral Large 4 pricing and API
On Mistral Studio, Mistral Large 4 costs $0.70 per million input tokens, $0.07 per million cached input tokens and $2.10 per million output tokens. The API model ID is mistral-large-4. Features listed in the docs: chat completions, function calling, structured outputs, document Q&A, batching, prefix, and the Agents and Conversations API with built-in tools. You can also call it through NVIDIA NIM and Hugging Face Inference Providers.
For context, that puts Mistral Large 4 well below closed frontier models on price and in the same range as big Chinese open models. Mistral also runs a European deployment it operates end to end under EU law, which matters to banks, governments and other buyers who care where data goes.
Mistral Large 4 license
Mistral Large 4 ships under the Mistral Ecosystem Open-Weight License. Hugging Face describes it as an MIT-derived license that adds limits on model-as-a-service offerings. In plain words: you can download the model, fine-tune it and run it inside your own products, but reselling it as a hosted API has extra conditions. Read the license on the model card before you build a hosting business on it.
How to run Mistral Large 4
- Fastest: call
mistral-large-4on Mistral Studio or try it in the Mistral playground. - vLLM: the NVFP4 checkpoint
mistralai/Mistral-Large-4-1T-A52B-NVFP4runs on 8 NVIDIA Blackwell GPUs with tensor and expert parallelism, plus a DSpark drafter for speed. - Transformers: use
AutoModelForMultimodalLMand launch withtorchrun --nproc-per-node 8. - llama.cpp: GGUF builds from Unsloth and ggml-org, for example
llama serve -hf ggml-org/Mistral-Large-4-1T-A52B-GGUF:Q2_K. - Dell Enterprise Hub: a ready deploy on 4× B300 GPUs.
Self-hosting is a data-center job. Even the 4-bit build needs a full multi-GPU node, so most teams will start with the API and move to their own hardware later. The weights and quants are in the Mistral Large 4 Hugging Face release.
Mistral Large 4 vs other open models
Model | Maker | Active / total params | Context | Weights |
|---|---|---|---|---|
Mistral Large 4 | Mistral AI | 52B / 1.05T | 1M | Open (Mistral Ecosystem license) |
LongCat-2.5 | Meituan | ~48B / 1.6T | 1M | Coming soon |
Kimi K3 | Moonshot AI | MoE | 1M | Open |
DeepSeek V4 Pro | DeepSeek | MoE | 1M | Open |
Pick Mistral Large 4 if you need security work without refusals, strong visual grounding, or an EU-hosted open model. Look at DeepSeek or Kimi if raw coding scores per dollar are all that matters.
Put Mistral Large 4 to work with a Sumus AI Employee
Yes, you can test Mistral Large 4 against the models you already use without writing a harness. This post was written by a Sumus AI Employee: it read Mistral's launch post, the docs and the Hugging Face release, pulled the numbers and built the chart above. Give a Sumus AI Employee a task like "run our 20 support prompts on Mistral Large 4 and Claude and show where each wins", and it plans the work, brings in other agents and hands back results your team reviews in the same chat.
What we're watching
- Specialized models built on Mistral Large 4 that Mistral says are coming.
- Gains from the RL run, which Mistral says is still in flight.
- Independent scores on Artificial Analysis and LMArena for the open-weight build.
FAQ
When was Mistral Large 4 released?
The public preview API launched on October 6, 2026. Open weights followed on October 29, 2026 on Hugging Face.
How many parameters does Mistral Large 4 have?
About 1.05 trillion in total, with 52B active per token (49B without embeddings and output layers), plus a 1.6B Pixtral vision encoder.
Can I run Mistral Large 4 locally?
Only on serious hardware. The official FP8 and NVFP4 builds target 8-GPU servers; community GGUF quants for llama.cpp exist but still need a lot of memory.
Does Mistral Large 4 support images?
Yes. It takes text and images as input and returns text. Mistral reports 42% on Dense 200 visual grounding, above GPT-6 Astra.
Is Mistral Large 4 the same as Le Chonk?
Yes. Mistral's own post says "Unofficially ML4, very officially: le Chonk."
Can a Sumus AI Employee use Mistral Large 4 results?
Yes. A Sumus AI Employee can research Mistral Large 4, compare it with other models on your tasks and report back in your team chat.
Update log
- — Nov 4: First published with specs, benchmarks, price and license from Mistral's launch post, Mistral docs and the Hugging Face release.