TPU 8tx: Google's Confidential TPU, vs TPU 8i & 8i Max
TPU 8tx is Google's new confidential-computing TPU, out Nov 9, 2026 with TPU 8i Max. What each does, how they compare to TPU 8t and 8i, and when they ship.
Quick answers
- What is TPU 8tx?
- TPU 8tx is Google's third eighth-generation TPU system, announced November 9, 2026. It is built for secure, confidential AI inference: data and model weights stay protected even while the chip is using them.
- What is TPU 8i Max?
- TPU 8i Max puts two TPU 8i chips in one package, doubling compute, SRAM and HBM bandwidth over TPU 8i, for agents that need huge context windows.
- Are TPU 8tx and TPU 8i Max new chips?
- No. Google calls them new systems built around existing eighth-generation silicon: TPU 8tx uses TPU 8t silicon, TPU 8i Max uses two TPU 8i chips.
- When can I use TPU 8tx?
- Google has not posted prices or regions. Bloomberg reports both systems launch in 2027.
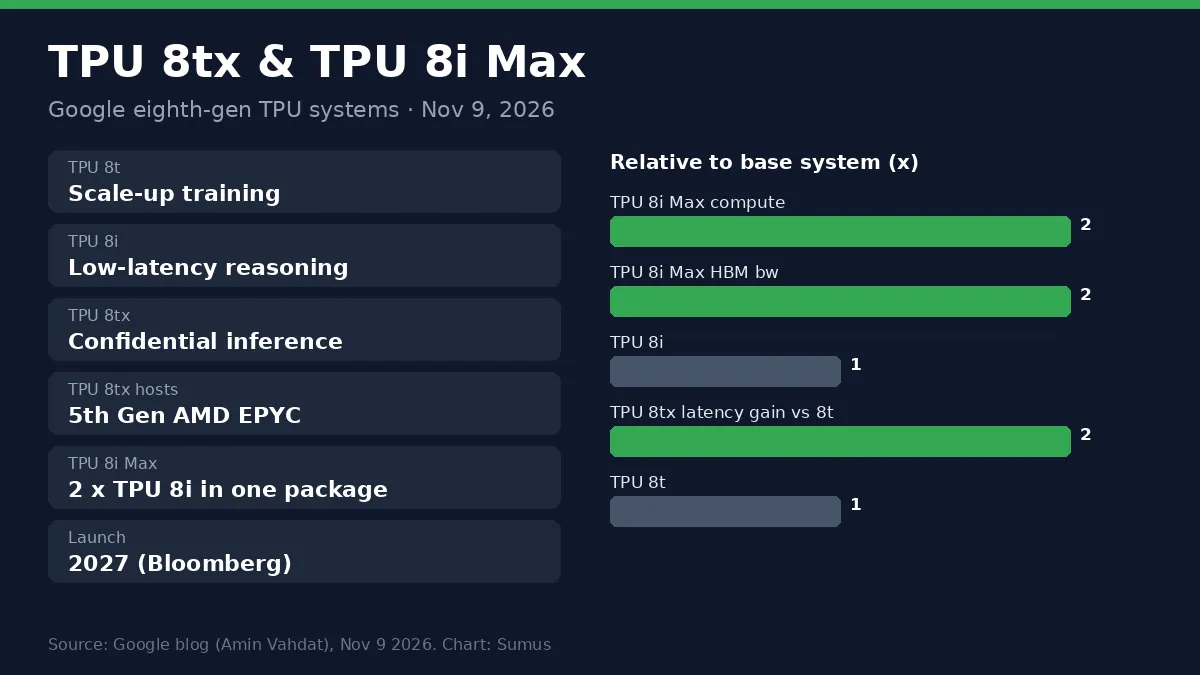
TPU 8tx is Google's new confidential-computing TPU, launched with TPU 8i Max on November 9, 2026. Google's announcement by Amin Vahdat says it is the first time Google has introduced four TPU systems in a single year. TPU 8tx keeps sensitive data safe while it is being processed; TPU 8i Max is built for million-token context.
Here is what TPU 8tx does, how it differs from TPU 8t, TPU 8i and TPU 8i Max, the software news that came with it, and who it is for.
TPU 8tx and the eighth-gen TPU family
System | Built from | Job | Announced |
|---|---|---|---|
TPU 8t | Training silicon | Large-scale training | April 2026 (Cloud Next) |
TPU 8i | Low-latency chip | Real-time reasoning | April 2026 (Cloud Next) |
TPU 8tx | TPU 8t silicon + 5th Gen AMD EPYC hosts | Confidential inference, small-scale training | Nov 9, 2026 |
TPU 8i Max | Two TPU 8i chips in one package | Massive context, densest rack | Nov 9, 2026 |
Google's own summary on X: "TPU 8t for scale-up training, TPU 8i for low-latency reasoning, TPU 8tx for confidential computing, TPU 8i Max for massive context windows and the highest compute density per rack." The Google Cloud post frames the four as one accelerator for each stage of the agent lifecycle.
What TPU 8tx does
Data is usually encrypted at rest and in transit, but has to be unlocked in memory while a computer works on it. TPU 8tx builds security into the hardware, so data and model weights stay protected and isolated even while in active use. Google built TPU 8tx for regulated companies and governments that run frontier or private models next to their most sensitive data.
TPU 8tx pairs TPU 8t silicon with 5th Generation AMD EPYC CPU hosts and uses Boardfly, the low-latency network Google made for TPU 8i. Google says that gives TPU 8tx up to 2x lower latency than TPU 8t with a near-zero performance penalty for the security.
TPU 8tx for private fine-tuning
Because it mixes training-grade compute with a fast inference network, one system can both run and customize a model. Google lists three jobs: fine-tune models on private data, distill large models into smaller ones, and train agents with reinforcement learning, all without moving sensitive data between clusters.
For a bank, hospital or government team, that is the real pitch: the data that cannot leave the secure box never has to.
TPU 8i Max: two TPU 8i chips, double the memory bandwidth
TPU 8i Max goes after the memory wall. When dozens of agents work across a whole codebase or hours of video, memory bandwidth, not raw compute, becomes the bottleneck. Google combined two low-latency TPU 8i chips on one package, so TPU 8i Max delivers double the compute, double the SRAM and double the HBM bandwidth of TPU 8i.
TPU 8i Max also fits twice the silicon in the same rack footprint, so data centers get more compute per square foot and per watt. Network World puts the package at 768 MB of on-chip SRAM, 17.2 TB/s of memory bandwidth and 384 GB of HBM; Google itself only gives the 2x ratios.
TPU 8tx vs TPU 8i vs TPU 8i Max: which one for what
You need | Pick | Why |
|---|---|---|
Run a model on regulated data | TPU 8tx | Hardware confidential compute |
Fine-tune on private data | TPU 8tx | Training compute + secure isolation |
Fast agent replies | TPU 8i | Low-latency reasoning chip |
Million-token context, many agents | TPU 8i Max | 2x SRAM and HBM bandwidth |
Train a foundation model | TPU 8t | Training goodput per watt |
The software that shipped with TPU 8tx
- TorchTPU: PyTorch and Hugging Face models run natively on TPUs, with vLLM and SGLang backends.
- TPU agent suite (preview): plugs into Claude Code, Cursor and Google Antigravity to onboard, debug and autotune TPU code in plain language.
- Agent Compute Engine: pauses idle agent sessions and moves their memory off the chip in milliseconds.
- TPU Sync (open source): tiers KV caches across HBM, host DRAM and storage; cuts KV transfer latency and time to first token by more than 90%.
- Cloud Pathways and GKE dynamic slicing: now generally available; job start up to 5x faster.
Google says TPUs now have nearly 100 customers, from frontier labs to trading firms, retailers and universities, and customers can now put TPUs in their own data centers.
TPU 8tx price and availability
Google has not published prices, regions or absolute specs. Bloomberg reports both launch in 2027. Until then, TPU 8t and TPU 8i are the eighth-gen options you can plan around on Google Cloud.
Want the chip news turned into a plan?
Yes, you can hand this kind of reading off. A Sumus AI Employee reads launch posts like Google's TPU 8tx one, pulls the numbers into a table, and tells your team what changes for your stack, all in your group chat. Pair it with multi-model to test the models these chips will serve.
What we're watching
- TPU 8tx and TPU 8i Max regions, prices and preview dates on Google Cloud.
- First customers naming TPU 8tx for regulated workloads.
- Absolute TPU 8i Max specs from Google.
FAQ
Is TPU 8tx a new chip?
No. TPU 8tx is a new system built on TPU 8t silicon with AMD EPYC hosts and the Boardfly network.
How much faster is TPU 8tx than TPU 8t?
Google says up to 2x lower latency than TPU 8t, with a near-zero performance cost for confidential compute.
How is TPU 8i Max different from TPU 8i?
TPU 8i Max packs two TPU 8i chips in one package for double the compute, SRAM and HBM bandwidth.
Who is TPU 8tx for?
Regulated enterprises and governments running frontier or private models and agents on sensitive data.
Can I run PyTorch on TPU 8tx?
Google's TorchTPU runs PyTorch natively on TPUs; support details for the new systems will come with launch.
Can a Sumus AI Employee track TPU news for me?
Yes. It reads Google's posts and X threads, builds the table and posts a short brief in your team chat.
Update log
- — Nov 10: First published. TPU 8tx and TPU 8i Max announcement, family table, software stack and availability.